How one Manhattan power room took down FAA air traffic control and disrupted 1,174 flights
· Matt Horn
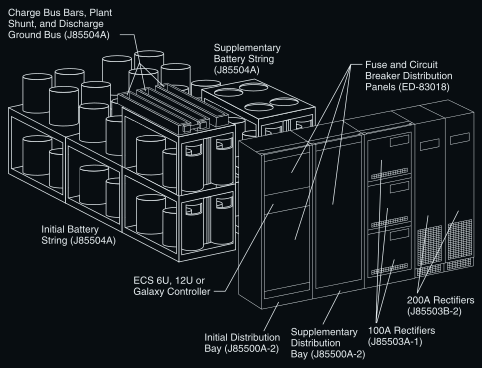
Lineage 2000 (J85500A-2) central office −48V DC battery plant, showing the cylindrical KS-20472 Round Cell strings on J85504A stands, overhead busbars, distribution bays, and rectifiers. Source: AT&T Product Manual 167-790-032 (Fig. 1-3, p. 1-6).At 4:40 p.m. on Tuesday, September 17, 1991, during the late-afternoon arrival rush across the Northeast, air traffic controllers at New York’s regional radar center and the towers at Kennedy, LaGuardia, and Newark lost their radar feeds, primary radios, and automated flight-handoff links at the same moment.123 With planes approaching all three airports, controllers had to guide commercial jets on short-range backup frequencies and manual tower-to-tower relays while the FAA halted airport traffic and 1,174 flights were canceled or delayed.234 Nothing had failed at the airports; instead, every primary and backup FAA landline for the New York metropolitan area ran through transmission bays powered by the 20th-floor DC power room of 33 Thomas Street, a 29-story windowless granite AT&T switching hub in Lower Manhattan.123 More than six hours earlier, a lead-acid battery reserve built to keep those lines running through power cuts had taken over when the room’s rectifiers tripped during a routine generator transfer, hiding the failure behind steady 48-volt output until the batteries ran dry.15 This post is part of an engineering safety series building on safety-standards work from a 2014 IEEE publication I co-authored.6
The 10:10 a.m. generator transfer
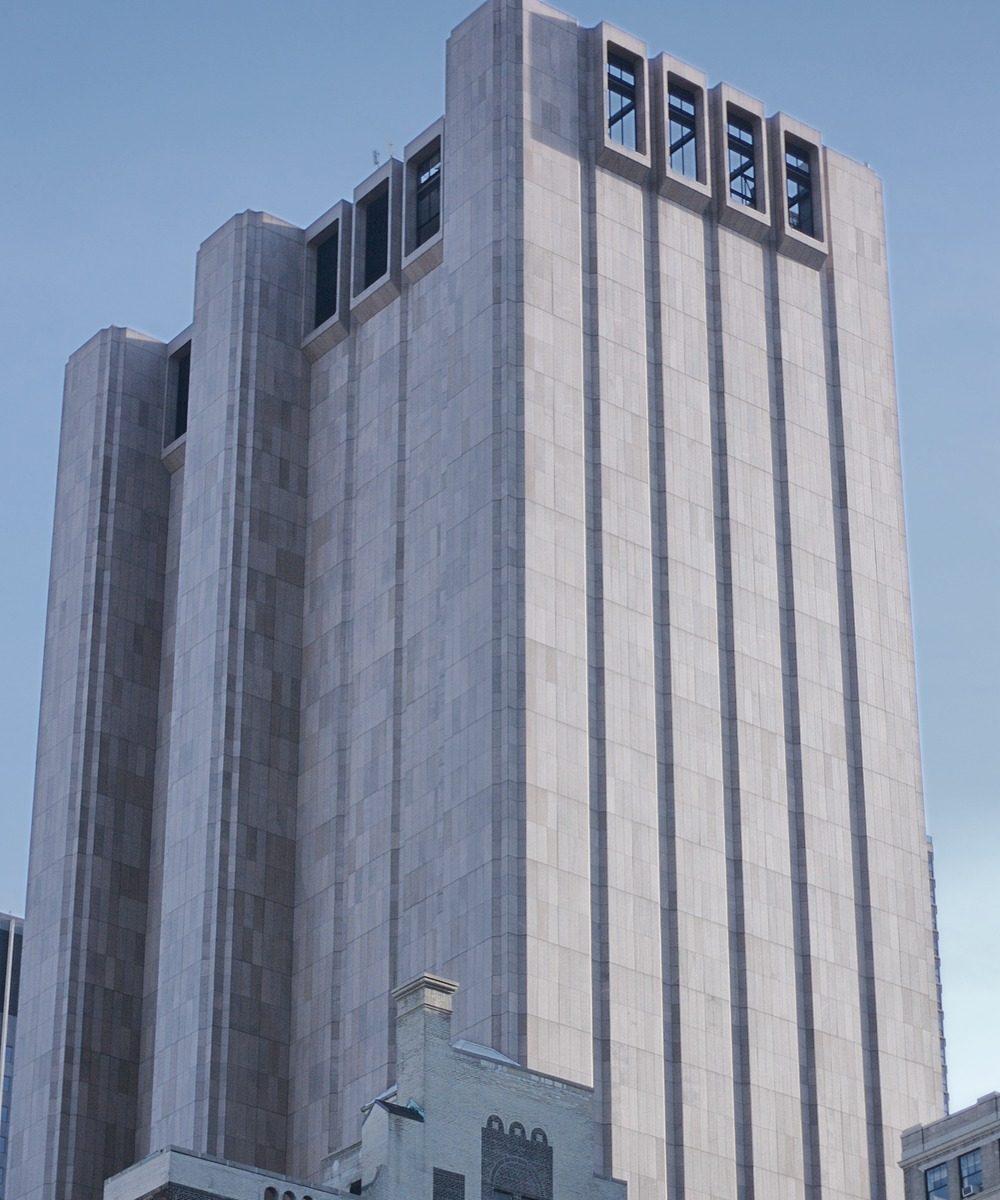

Between 6:00 and 7:00 a.m. EDT, Consolidated Edison contacted AT&T’s Building Operations Group under a voluntary peak-load power-sharing agreement and asked the facility to transfer off commercial street power for the day.15 At 10:10 a.m., the AC power supervisor threw the transfer switch, moving 33 Thomas Street from Con Edison street AC to the building’s internal diesel generators.15
During the transfer, a voltage spike on the AC feed reached the 20th-floor power room, which supplied direct current to the building’s high-capacity DS3 (45-megabit T3) fiber and coaxial transmission bays.1 That voltage spike tripped an overload protection relay that had been misadjusted during recent plant modernization, knocking the room’s AC-to-DC rectifiers offline.15
In a central office DC power plant, the rectifiers and the battery strings sit in parallel across the main 48-volt (-48V DC) busbars. Under normal operation, the rectifiers hold the bus slightly above the resting voltage of the lead-acid cells, keeping the batteries topped up while supplying the live current drawn by the switching bays. When the 20th-floor rectifiers opened at 10:10 a.m., bus voltage settled a few volts down onto the battery plateau and stopped falling.
No circuit dropped, and every trunk kept running at full capacity. The building’s three 4ESS toll switches ran on separate power plants and were unaffected, while the 20th-floor batteries carried all of the high-capacity DS3 transmission bays.1 The leased AT&T data lines, remote radio links, and voice trunks serving the FAA’s New York Terminal Radar Approach Control (TRACON) facility in Hempstead, Long Island, and the control towers at Kennedy, LaGuardia, and Newark continued operating normally.1234 Inside 33 Thomas Street, the 20th-floor batteries had begun a six-and-a-half-hour discharge.15
Four broken links in the alarm path
For a six-hour battery reserve to buy six hours of repair time, news of the rectifier trip has to reach an operator who can clear the relay and bring the rectifiers back onto the bus while the cells are still near full charge. At 33 Thomas Street, the fault path from the 20th-floor rectifiers to a human responder had to cross four physical and organizational links on the 20th and 14th floors. As AT&T Vice President of Network Operations William J. Carroll disclosed three days later, all four were open.57
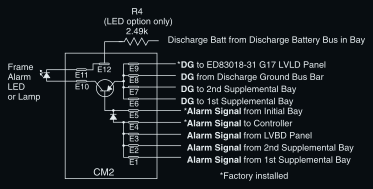
CM2 alarm circuit pack schematic in an AT&T Lineage 2000 battery plant, driving both the local Frame Alarm LED or Lamp and the downstream Alarm Signal to Controller (E4). Source: AT&T Product Manual 167-790-032 (Fig. 4-8, p. 4-20).1. The burned-out indicator lamp
An indicator bulb that would have signaled the fault was burned out.57 (AT&T’s October 2 synopsis added that a technician walking through the 20th-floor power room still would have seen a local POWER alarm inside the room, though no one walked the floor until the evening shift.1) Without a lamp-supervision check or a routine lamp test before a generator transfer, a burned-out bulb stays dark during a fault just as it does under normal operation.
2. The missing 25-inch jumper strap on the 14th floor
1AESS MCC), showing the indicator lamp rows, alarm keys, and wire-wrap bays typical of AT&T switching hubs. Photo: Sirgorpster (CC BY-SA 4.0).
On the 14th floor, a 25-inch metal strap was missing in the alarm control base, immobilizing the secondary alarm circuit.57 According to the FCC Common Carrier Bureau’s subsequent investigation, that alarm, scheduled for replacement in October, had not been checked since June 1990.17
Because the alarm wire carried current only during a fault, an open 25-inch strap produced the same electrical state at the receiving end as a healthy power plant. With the circuit left unchecked for fifteen months, the unbridged terminal posts reported zero fault current whenever the strap was absent, and the monitoring panel treated that silence as normal operation.
3. The mechanically clamped bell
Even with the bulb dead and the 25-inch strap missing, a local audible alarm bell did receive current when the rectifiers tripped.5 As Carroll explained in his September 20 briefing, on the 14th floor “the alarm was clamped so that it was ringing lightly, but not loud enough to be audible.”5 A subsequent House subcommittee investigation of internal AT&T records reported that personnel had muted central-office alarm bells by tightening the audio alarm bell adjustment screw.5
Because the outage followed a string of 1990 and 1991 telephone network crashes caused by signaling-software bugs, later retellings frequently blame software for disabling the central-office warning horn.4 At 33 Thomas Street, no software was involved; personnel had muted the bell mechanically during earlier operations.5 When a local alarm bell rings continuously during maintenance or fault clearing without an automatic re-arming silence timer, tightening a bell screw or clamping a gong is a common floor workaround against constant noise.
4. The unmonitored watch handoff
With the indicator bulb dead, the 25-inch strap missing in the 14th-floor alarm control base, and the alarm bell muffled, the only remaining way to catch the rectifier trip was for a power technician to walk through the power rooms and inspect the rectifiers in person.54 Standard AT&T procedure required the direct-current power supervisor to dispatch technicians to check each power plant whenever the building switched from Con Edison street power to internal generators. The building had made that cutover four times earlier that summer without incident.154
On the morning of September 17, the DC power supervisor and the building’s dedicated power technicians were off-site at 811 10th Avenue in Midtown Manhattan, roughly 15 minutes away, attending a training class on a new computerized power alarm system scheduled for cutover at 33 Thomas Street in October.15 Fifty-two other technicians inside 33 Thomas Street were qualified to check the power rooms, and the AC power supervisor who threw the 10:10 a.m. transfer switch was in the building, but according to AT&T, the absent DC supervisor neither dispatched a substitute nor handed off the post-transfer walk-through.154
The larger gap was the handoff architecture. In September 1991, 33 Thomas Street had no remote power-plant telemetry wired to a regional network operations center.1 Every high-capacity trunk passing through the building depended on manual floor walk-throughs after a generator transfer, yet scheduling the entire DC power crew into an off-site class on the new alarm system triggered no automated handoff block and no remote watch transfer.154 The building’s 20th-floor power plant was running on battery reserve with nobody assigned to walk the floor and no wire leaving the building to report it.
4:30 p.m.: why the manual restart failed
For more than six hours after the 10:10 a.m. transfer, the 20th-floor batteries held the bus near 48 volts. Lead-acid cells do not lose voltage steadily as they drain; they hold a flat voltage plateau across almost their entire capacity and then drop off a steep cliff in the final minutes.
At 4:30 p.m. EDT, 6 hours and 20 minutes after the diesel cutover, a power-qualified communications technician coming on duty for the evening shift saw a visual low-voltage battery display in an unstaffed area on the 12th floor and attempted to cut the 20th-floor plant back from batteries to AC power.15 That restart attempt failed immediately.15
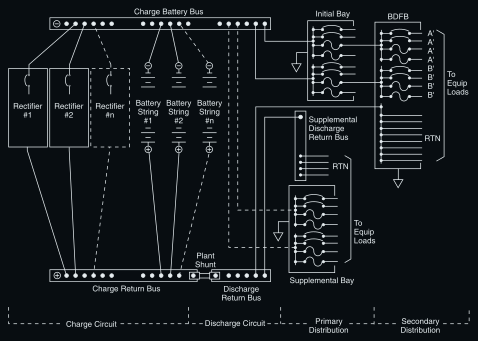
Lineage 2000 battery plant showing how Rectifier #1–#n, Battery String #1–#n, and the primary/secondary equipment distribution bays sit in parallel across the Charge Battery Bus. Source: AT&T Product Manual 167-790-032 (Fig. 1-2, p. 1-5).As AT&T explained in its post-incident synopsis, “the batteries had been discharged to a point where they would not physically accept recharging current without being disconnected from the facilities they were supporting.”1 Reconnecting offline rectifiers onto a deeply discharged 48-volt battery bank (KS-20472 / C&D flooded lead-acid cells) while full central-office load is still attached creates an electrical surge: the depleted cells demand a large charging current at the same moment the DS3 transmission bays draw their full steady-state load. Without automatic restart capability (which AT&T noted the existing 20th-floor plant lacked), technicians could not bring the plant back online while the transmission bays remained connected.1
Ten minutes after the failed cutback attempt, at 4:40 p.m. EDT, the 20th-floor battery reserve expired.15
4:40 p.m.: New York TRACON and the seven-hour recovery
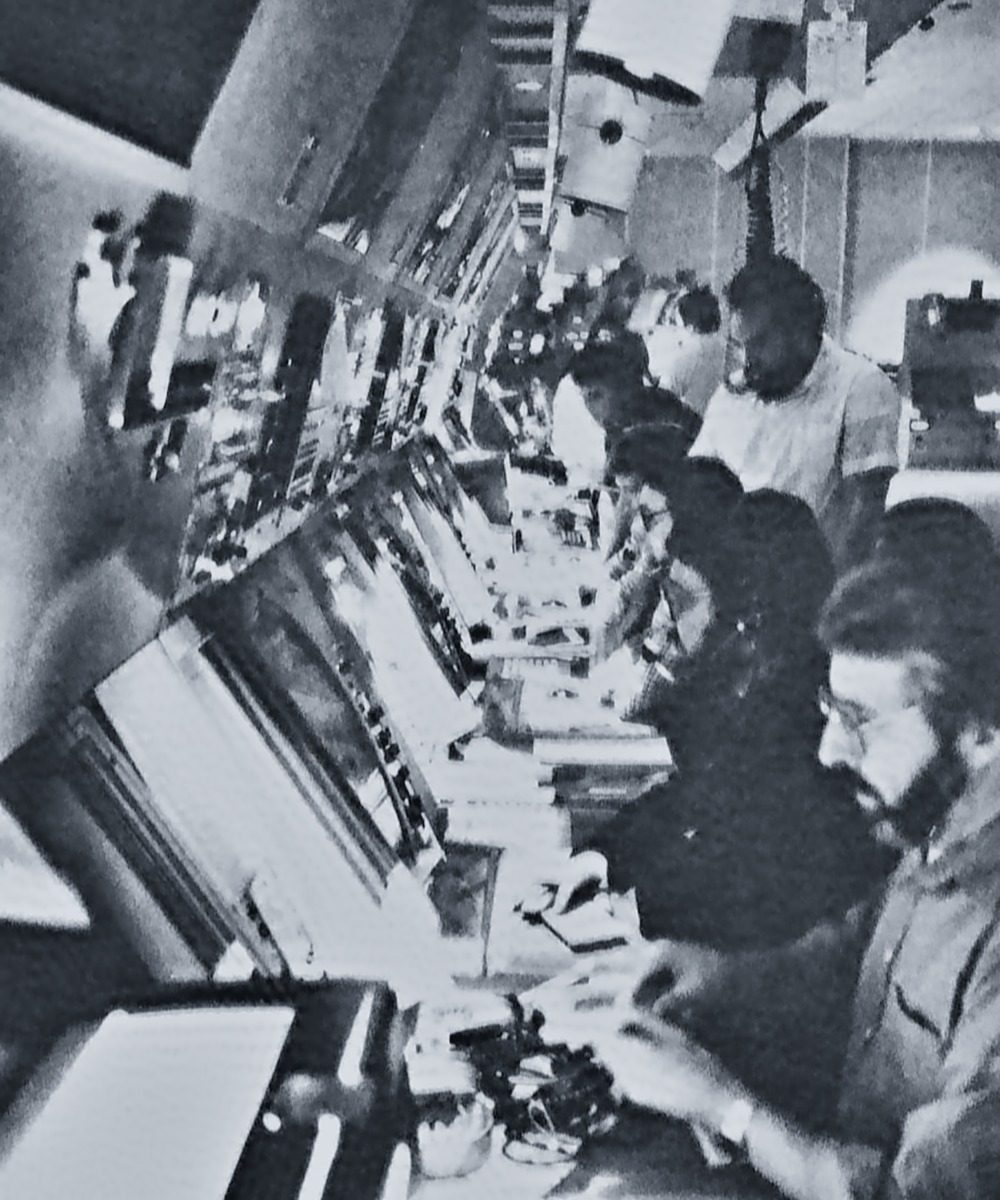
ARTS IIIA (DEDS FA-8320) radar scopes. Source: Sperry Univac / J. ATC (1981).Between 4:40 and 4:50 p.m. EDT, as the 20th-floor bus fell below operational cutoff, the DS3 and other high-capacity transmission facilities inside 33 Thomas Street shut down.13
The primary and backup FAA landlines for New York TRACON and the three airport towers ran through those bays, carrying remote radar and beacon targets into TRACON’s Sperry Univac ARTS IIIA Sensor Receiver and Processor (SRAP) and Communications Multiplexer Controller (CMC) units alongside voice and flight-plan links.234 The blackout also severed communications linking the New York, Boston, and Washington Air Route Traffic Control Centers, and the FAA at first believed it had lost all of the 90 or more radio and data links into New York Center, though a few were later restored. A backup system came up fairly quickly at the TRACON, but controllers there could do little with New York Center cut off.24 Controllers had to sequence approaching aircraft on short-range backup frequencies and manual tower-to-tower relays, halting departures and arrivals across Kennedy, LaGuardia, and Newark from roughly 5:00 p.m. until 9:00 p.m. EDT.2384 By the time traffic cleared, 1,174 flights had been canceled or delayed, affecting 85,000 passengers, and more than 5 million domestic and international calls had been blocked.274
Inside 33 Thomas Street, recovery required more than closing the 20th-floor rectifiers back onto the bus. Because the depleted battery strings and the connected transmission bays together drew more current than the rectifiers could accept from a cold start, engineers had to physically disconnect all supported equipment from the 20th-floor power plant before they could manually reset the rectifiers at 6:00 p.m.:1
First pass-through reroute. 144 non-terminating DS3 (T3) pass-through trunks carrying ~19,200 voice circuits and ~1,400 private-line T1s are restored via alternate routing.1
Full load disconnect & rectifier reset. Engineers physically disconnect all downstream equipment from the 20th-floor plant so the rectifiers can be manually reset without tripping on recharge and load inrush, then begin staged reconnection.1
Staged trunk recovery (51% dom / 56% int’l). Cross-connect realignment and circuit restoration continue across the high-capacity transmission bays.1
Shifting blame from the floor to the supervisor
In the immediate aftermath of an infrastructure failure, organizations almost always publish what safety researchers Richard Cook, David Woods, and Sidney Dekker call the “first story”: a narrative that stops at the last human hand near the controls and declares operator error.9
On Wednesday, September 18, 1991, one day after the blackout, AT&T management told reporters that human error had caused the outage because “a supervisor and technicians at the site in lower Manhattan” had “failed to read several alarms properly.”4 That explanation was clean, bounded, and required no examination of why a single 20th-floor power room could sever all three New York airports or why the building’s alarm circuit had gone untested since June 1990.
Blaming the floor technicians lasted one day. Officials from the Communications Workers of America (CWA), representing the building’s technicians, challenged the company’s account and pointed out that the technicians had been at the off-site alarm class while the building’s alarms failed.5 AT&T Vice President William J. Carroll held a 75-minute briefing on Friday, September 20, to retract the accusation against the technicians: “The technicians were not at fault and we apologize for any implication.”54
Even then, AT&T management did not abandon the human-error framing. The company shifted fault one level up the hierarchy to the off-site supervisor and local procedures (“If this supervisor had followed the process outlined, this would not have happened”). In a letter to the FCC, AT&T Senior Vice President Kenneth Garrett said the company was “deeply distressed by the lapses in procedure” and noted that the failure was not a systemic breakdown of the AT&T network.54 Yet the remedial commitments AT&T announced by October 1991 and the regulatory actions that followed had to address the underlying hardware and monitoring architecture directly:
- Auto-restart rectifiers and 50% load diversification: AT&T scheduled the 48-volt power plant for replacement by year-end with hardware capable of automatic restart and committed to re-engineering central-office power distribution (targeted for March 1992 at 33 Thomas Street) so that no single power plant could feed more than 50 percent of an office’s high-capacity DS3 facilities.1
- Out-of-building telemetry to Conyers, Georgia: AT&T began installing the new redundant power alarm system at 33 Thomas Street, wired to both local building panels and its remote surveillance center in Conyers, Georgia. It also stepped up plans to spend $200 million nationwide over 12 months to upgrade power-system reliability and backup.1
- Mandatory outage reporting and path diversity: FCC Common Carrier Bureau Chief Rick Firestone said the Commission had decided not to impose monetary fines because investigators found no malicious intent.7 In December 1991, the FCC chartered the Network Reliability Council to recommend measures to prevent or limit public network outages, and in February 1992, the FCC ordered carriers to notify the Commission within 90 minutes whenever an outage affected at least 50,000 customers for 30 minutes or longer.210 Meanwhile, the FAA began procuring its Leased Interfacility NAS Communication Systems (LINCS) program, which it expected to prevent single-point leased-line failures across air-traffic facilities.2
When a postmortem stops at “be more careful”
Every piece of machinery in the 1991 collapse has a direct equivalent in modern distributed software and AI infrastructure. We no longer wire 25-inch metal jumper straps across 14th-floor terminal blocks, but we build the same failure topology whenever we pair large capacity buffers with alerts that fire only when something reports an error.
1. Buffers hide upstream failures until they run out
A six-and-a-half-hour battery bank, a deep request queue, a generous retry budget, a long-TTL cache layer, and long-lived authentication tokens all perform the same job: they keep downstream consumers running when upstream supply drops out. That decoupling makes a system resilient against brief glitches, and it also hides sustained upstream failure from anyone watching downstream health.
When an upstream dependency dies, a downstream service backed by a multi-hour buffer continues reporting 100 percent success and flat latency. That holds true whether the failed upstream component is a pair of 20th-floor rectifiers, an identity control plane issuing long-lived tokens, or a data control plane behind a warm cache. If an on-call dashboard only measures downstream customer-facing errors, a six-and-a-half-hour buffer hides the upstream failure for six hours and twenty minutes and pages the engineer at 4:30 p.m. with ten minutes of reserve left.
2. Restarting an empty system takes more capacity than normal load
Distributed software and AI serving systems hit the same cold-start wall that prevented the 4:30 p.m. rectifier cutback at 33 Thomas Street, a pattern systems researchers call a metastable failure.11 When every key in a cache tier or GPU prompt-cache cluster expires after an upstream outage, or when queued agent and client retries flush against a recovering backend at once, the recovering service has to refill the empty buffer while serving live traffic. That combined demand (charging current + load current) immediately trips the recovering service’s overload protection again.11 Unless a buffered system can automatically shed load or rate-limit its own refill during recovery, restarting it after an outage that drains the buffer requires disconnecting load by hand.
3. A dead service cannot report its own failure
The missing 25-inch strap, on a 14th-floor alarm circuit nobody had checked since June 1990, went undetected for the same reason the burned-out indicator bulb went unnoticed: the alarm circuit sent a signal only when a fault occurred.57 When the alarm path itself broke, nothing happened.
Software teams build the same trap whenever they alert on error rates alone. When a team pages on error_rate > 1% and a service goes down completely, stops accepting requests, or loses its metrics connection, the error rate never crosses the threshold and the alert never fires.
In critical systems, it is much safer to measure continuous successful operation and trip a fail-safe as soon as that positive signal stops arriving. When an external monitor checks that a system is actively completing work, or verifies a continuous watchdog heartbeat leaving the building like the telemetry link AT&T later wired to Conyers, Georgia, any break in the chain trips an alert immediately. A missing 25-inch strap, a burned-out bulb, or a crashed telemetry daemon fails loud on day one instead of waiting fifteen months for a generator transfer.
When AT&T’s initial statement on September 18 blamed personnel who “failed to read several alarms properly,” and its later statements blamed the supervisor for not following procedure, AT&T treated human vigilance as the control that was supposed to protect New York’s airports.4 No amount of carefulness lets a technician hear a muffled bell from Midtown Manhattan, spot a dead bulb on an unmonitored lamp circuit, or notice a missing jumper strap on an untested frame. AT&T’s own remediation plan replaced vigilance with engineering: splitting power loads so no plant fed more than half of an office’s high-capacity facilities, replacing the plant with one built to restart, and wiring the new alarm system to a surveillance center outside the building.1 Controls like these make routine generator transfers and live maintenance safe to run without gambling regional air traffic on nobody making a mistake.
AT&T Corporate Media Relations, “FOR THE RECORD” synopsis of the September 17, 1991 New York service disruption, posted by Mike Eastman (AT&T Bell Laboratories, 4ESS Development) to
comp.dcom.telecomon October 2, 1991, and archived in ACM RISKS Digest Vol. 12, Issue 43 (October 7, 1991). AT&T’s October 2 synopsis refers to a tripped rectifier in the singular during the 10:10 a.m. transfer (and plural"rectifiers"during the 6:00 p.m. reset) and states that all six power technicians plus their supervisor were at the off-site alarm training class, whereas Vice President William J. Carroll’s September 20 briefing (Note 3) specified that two rectifiers failed and counted three power technicians at the class. ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎U.S. General Accounting Office, Telecommunications: Interruptions of Telephone Service, GAO/RCED-93-79FS (March 1993), pp. 4, 11; see also GAO, Information Superhighway: An Overview of Technology Challenges, GAO/AIMD-95-23 (January 1995), ch. 1. ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎
“Phone failure causes closing of N.Y. airports,” The Baltimore Sun, September 18, 1991. ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎
Cindy Skrzycki and Don Phillips, “Human Error Led to Outage, AT&T Says; Technicians Failed to Heed Alarms,” The Washington Post, September 19, 1991; see also The Wall Street Journal, “AT&T Tells FCC a Lapse In Procedure Led to Outage,” October 1, 1991, p. C18 (excerpted in ACM RISKS Digest Vol. 12, Issue 43), and William L. Benoit and Susan L. Brinson, “AT&T: ‘Apologies are not Enough’”, Communication Quarterly 42, no. 1 (Winter 1994): 75–88. ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎
Alan Gersten, “AT&T discloses cause of power failure,” United Press International (UPI), September 20, 1991 (reporting the briefing by AT&T Vice President William J. Carroll); Cindy Skrzycki, “AT&T Admits Technicians Weren’t at Fault in Outage; Union Defends Its Members in Breakdown,” The Washington Post, September 20, 1991; and “AT&T Alarms Disabled in Outage, Panel Says,” The Washington Post, October 1, 1991 (reporting House subcommittee findings that personnel muted the alarm bell by tightening the audio alarm bell screw). ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎
W. Eric Wong, Tej Gidvani, Alfonso Lopez, Ruizhi Gao, and Matthew Horn, “Evaluating Software Safety Standards: A Systematic Review and Comparison,” in 2014 IEEE Eighth International Conference on Software Security and Reliability-Companion (SERE-C) (San Francisco, CA: IEEE, 2014), pp. 78–87, doi:10.1109/SERE-C.2014.25. ↩︎
“FCC blames N.Y. outage on AT&T; Report cites human, equipment errors,” The Baltimore Sun, November 9, 1991 (reporting the FCC Common Carrier Bureau investigation and Bureau Chief Rick Firestone’s findings). ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎ ↩︎
Peter G. Neumann, “AT&T phone failure downs three New York airports for four hours,” ACM RISKS Digest Vol. 12, Issue 36 (September 18, 1991). ↩︎
Sidney Dekker, The Field Guide to Understanding ‘Human Error’, 3rd ed. (Boca Raton, FL: CRC Press, 2014), pp. 1–16, building on the “First Story” vs. “Second Story” framework introduced by Richard I. Cook, David D. Woods, and Charlotte Miller in A Tale of Two Stories: Contrasting Views of Patient Safety (Chicago: National Patient Safety Foundation, 1997) and David D. Woods, Sidney Dekker, Richard Cook, Leila Johannesen, and Nadine Sarter, Behind Human Error, 2nd ed. (Farnham, UK: Ashgate / CRC Press, 2010). ↩︎
Federal Communications Commission, Report and Order: Amendment of Part 63 of the Commission’s Rules to Provide for Notification by Common Carriers of Service Disruptions, FCC 92-58, CC Docket No. 91-273, 7 FCC Rcd 2010 (adopted February 13, 1992; released February 27, 1992). ↩︎
Nathan Bronson, Abutalib Aghayev, Aleksey Charapko, and Timothy Zhu, “Metastable Failures in Distributed Systems,” in Proceedings of the Workshop on Hot Topics in Operating Systems (HotOS ‘21) (New York: ACM, 2021), pp. 221–227, doi:10.1145/3458336.3465286; see also Lexiang Huang et al., “Metastable Failures in the Wild,” in Proceedings of the 16th USENIX Symposium on Operating Systems Design and Implementation (OSDI ‘22) (USENIX, 2022), pp. 73–90. ↩︎ ↩︎